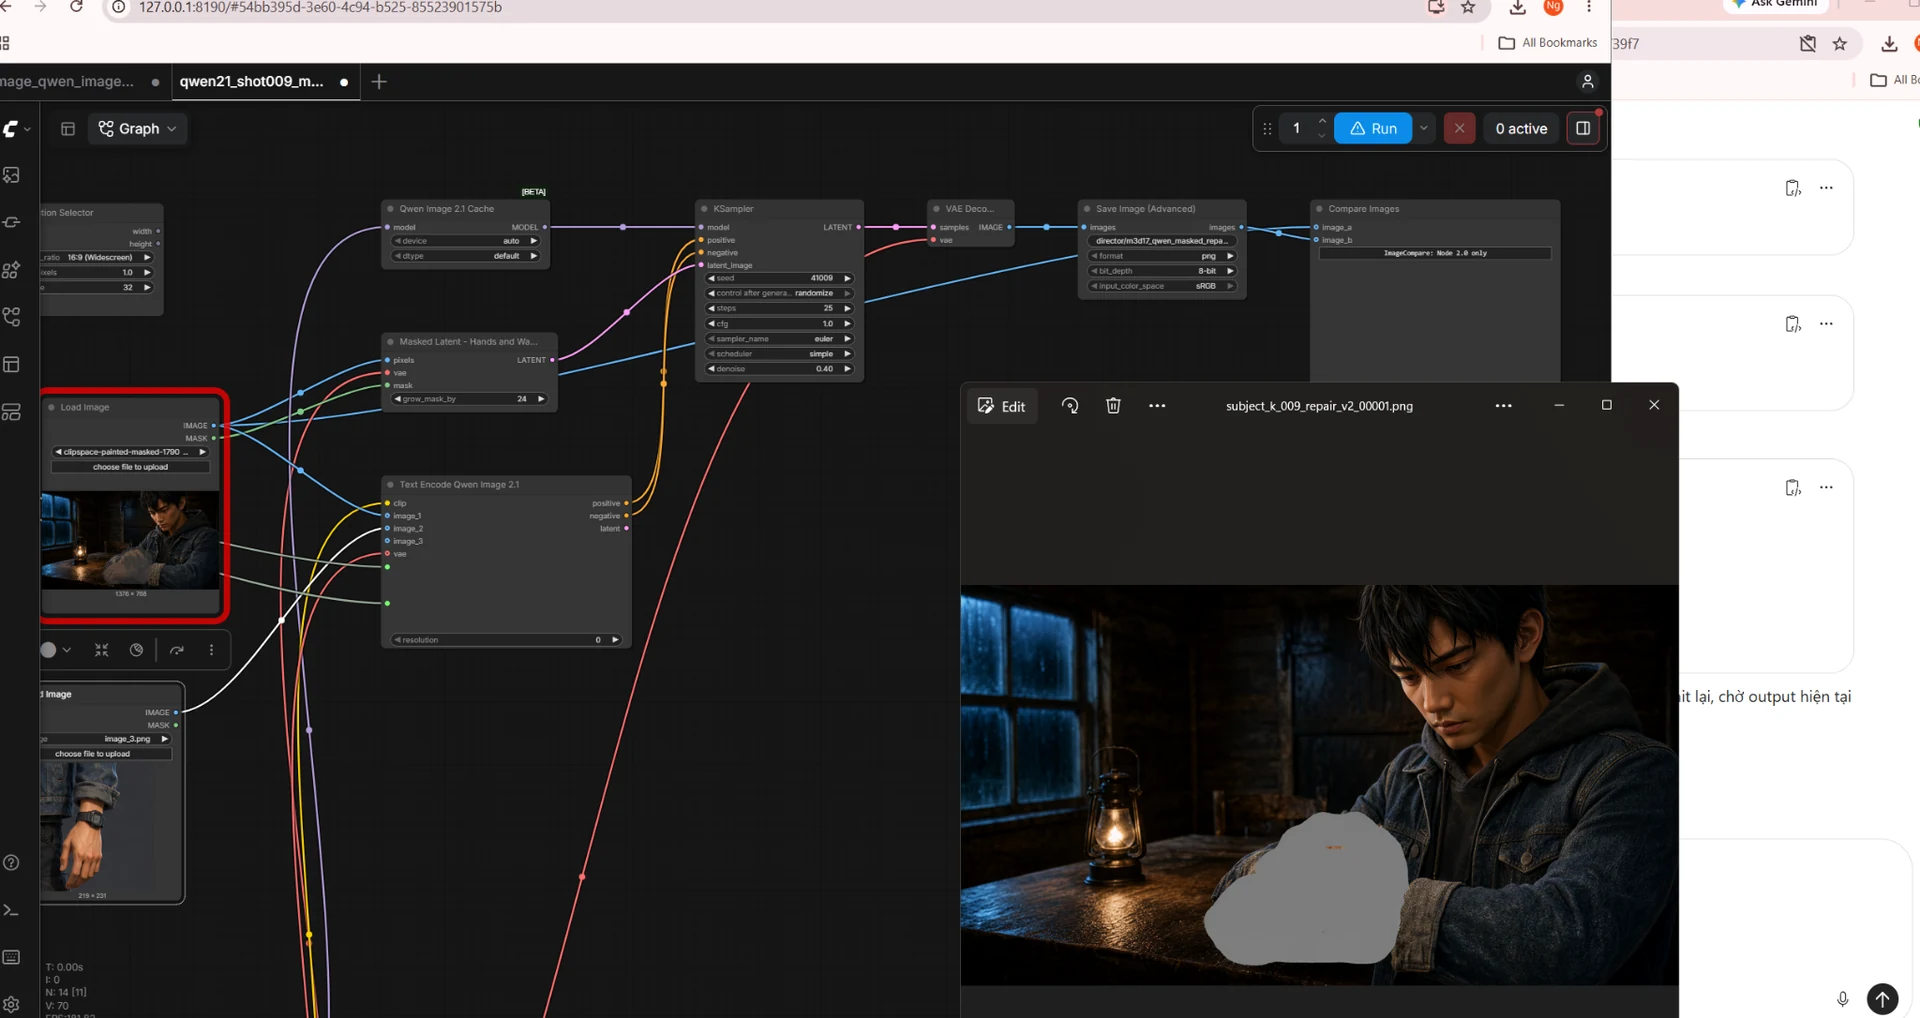
Masked Repair production graph
The captured graph shows image and mask inputs, masked latent preparation, Qwen-Image 2.1 encoding, sampling, VAE decoding, save output, and image comparison.
Qwen-Image 2.1Local executionRegion maskCompare output
Narrativera turns scripts into governed, production-ready AI film workflows. One intelligent layer for shot design, continuity, model orchestration, generation, recovery, quality control, voice, and sound.
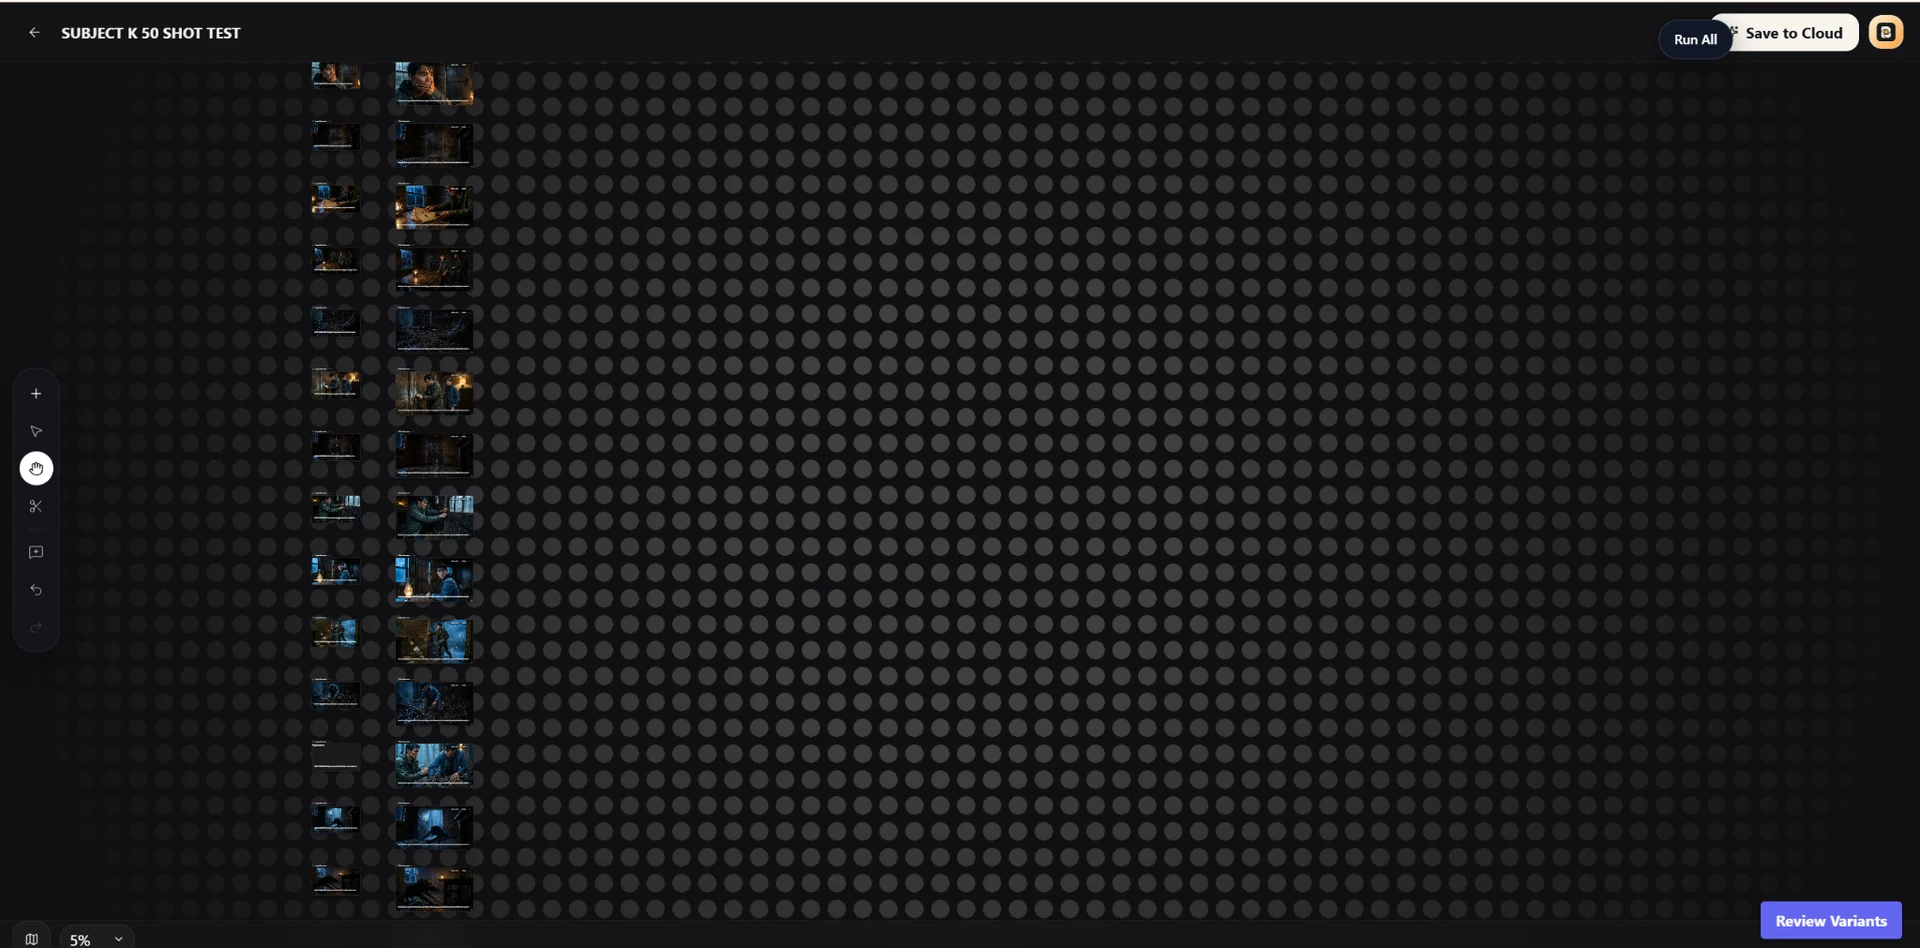
Subject K is produced through a visual graph that carries approved references into shot-level image and video generation. The production view below is captured from the working Flowboard environment.
Qwen-Image 2.1 is used inside a local ComfyUI masked-repair graph to target a selected region while retaining the approved composition, setting, lighting, wardrobe, character reference, and surrounding detail.
The captured graph shows image and mask inputs, masked latent preparation, Qwen-Image 2.1 encoding, sampling, VAE decoding, save output, and image comparison.
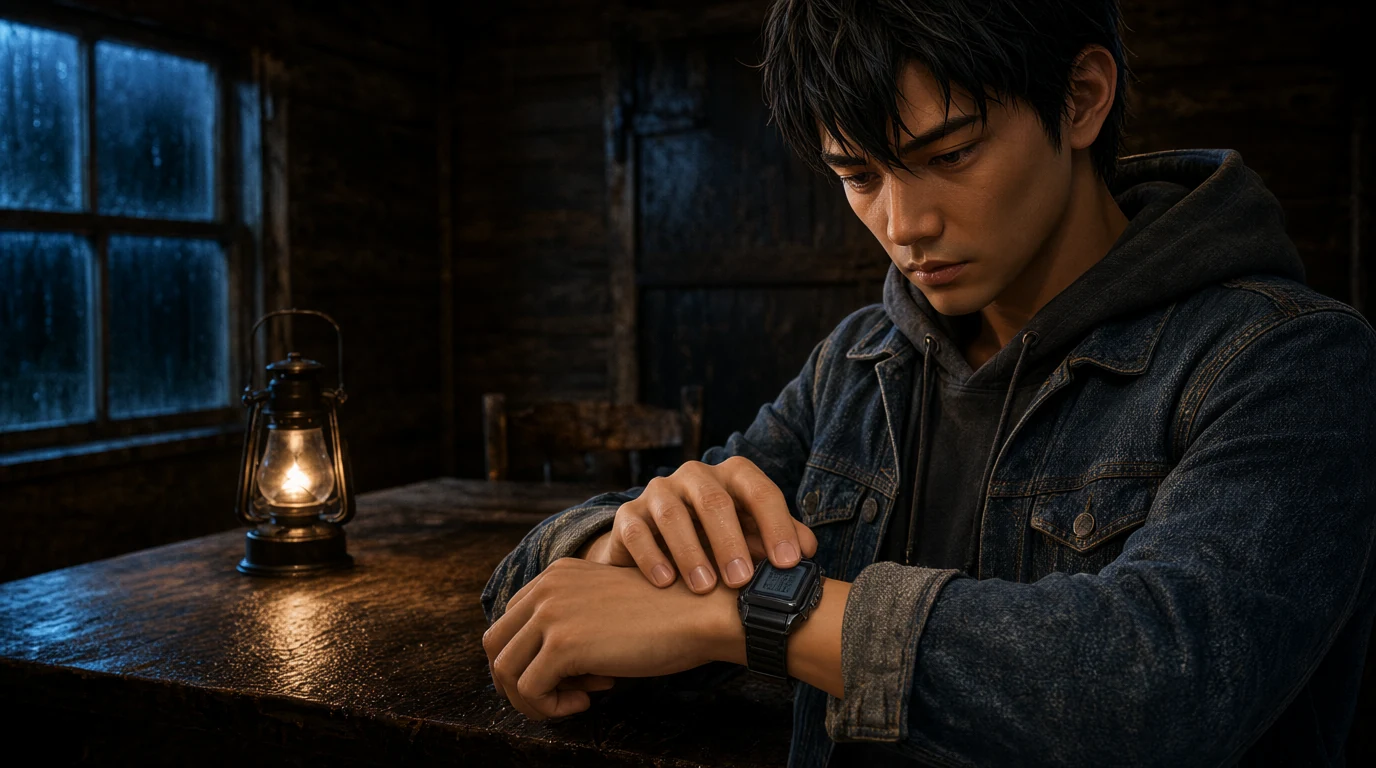
The repaired frame preserves the cabin composition, blue window light, oil-lamp warmth, denim wardrobe, and wristwatch detail.
Masked repair is treated as a resumable production stage. The approved frame remains the source of truth while only the selected region is regenerated and returned to quality control.
Compelling work demands more than access to a model. Narrativera keeps narrative decisions intact through references, revisions, retries, providers, and finishing.
Scripts become scene logic, shot contracts, visual intent, continuity constraints, and model-ready tasks.
Preserve identity, wardrobe, locations, props, and framing language across long-form sequences.
Route work to local or cloud systems by capability, quality, availability, and cost.
Repair selected regions, regenerate failures, and resume without discarding approved work.
Coordinate voices, dialogue, sound design, music, and delivery assets in one graph.
Keep checkpoints, routing choices, attempts, outputs, and approvals visible.
Narrativera gives creative intent a durable technical form, then carries it through every stage of an AI-native production.
Structure story intent and dramatic continuity
Convert scenes into executable shot contracts
Lock characters, locations and visual anchors
Route image and video tasks across models
Repair, retry, resume and quality-control outputs
Assemble voice, sound, music and delivery assets
Under active development in Ho Chi Minh City, Vietnam. Open to model, infrastructure, research, and technology partnerships focused on coherent, reliable, creatively controllable generative media production.